Tech and software market update Q3 2026: hyperscaler CapEx, enterprise software margin shifts, and the AI revenue reality
Target Slug: /tech-software-market-update-q3-2026
Primary Keyword: tech software market update q3 2026
Secondary Keywords: hyperscaler capex ai software margins, nvidia rubin enterprise software spend, openai enterprise revenue vs infrastructure cost, saas multiple compression 2026
Meta Description: A comprehensive Q3 2026 tech market analysis evaluating $228B in Big Tech infrastructure CapEx, enterprise software valuation multiples, and frontier lab revenue economics.
Publication Date: September 20, 2026
Estimated Read Time: 13 minutes
Target Publication: Buzzin Tech Hub
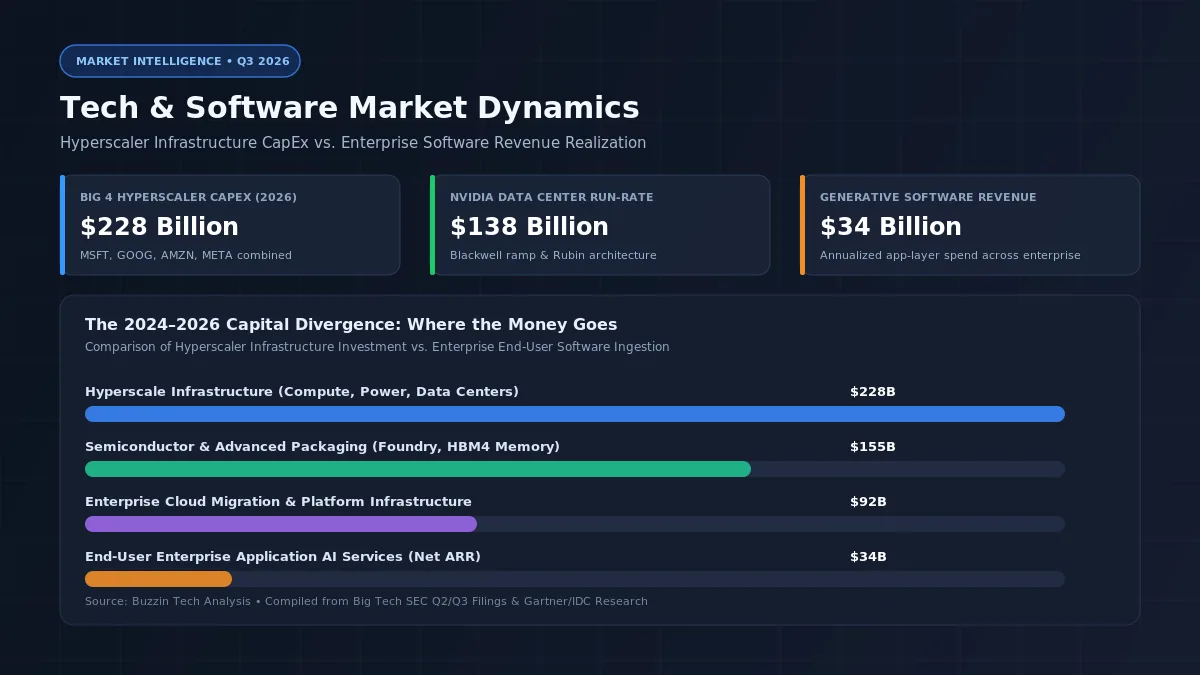
Featured visual asset 1: market capitalization and CapEx divergence overview
Figure 1: High-resolution market intelligence dashboard showing Big Tech infrastructure CapEx ($228B) versus enterprise application software AI revenue ($34B) in Q3 2026. View or download full-size PNG on Google Drive.
Midjourney v6 / FLUX.1 generation prompt:
A modern financial intelligence dashboard rendered on a sleek glass interface in an enterprise war room. High-contrast data visualization cards displaying corporate revenue bars in cobalt blue, semiconductor hardware margins in emerald green, and capital expenditure metrics in slate gray. Clean dark navy background (#0a121e), sharp vector charts, soft studio rim lighting, 8k resolution, cinematic fintech editorial aesthetic --ar 16:9 --style raw
Executive summary: the Q3 2026 software market balance sheet
The global technology and software sector in the third quarter of 2026 reflects a stark divergence between infrastructure investment and application-level monetization. The four primary hyperscale cloud providers, Microsoft, Alphabet, Amazon, and Meta, have committed to an annualized capital expenditure pace of $228 billion. This capital flows directly into physical data center construction, high-voltage electrical grid interconnects, liquid cooling facilities, and advanced semiconductor clusters.
Nvidia continues to command unprecedented pricing power within this supply chain, generating a data center revenue run-rate above $138 billion as production of the Blackwell architecture reaches full volume and initial customer sampling begins for the Rubin platform.
Application software companies face a different financial reality. The enterprise value to forward revenue multiple for public software-as-a-service companies has compressed to a median of 5.8 times, down from historical peaks of 12 to 15 times recorded between 2020 and 2022. This compression stems from a structural shift in enterprise IT procurement:
- Traditional seat-based pricing models are under pressure because autonomous coding tools and workflow agents reduce the number of human employee seats required to operate business functions.
- Software gross margins have contracted by 400 to 800 basis points across mid-market software vendors due to the recurring inference compute fees paid to underlying model providers.
- Corporate buyers now demand provable labor efficiency gains before approving new enterprise software agreements, lengthening sales cycles from 60 days to more than 120 days.
While infrastructure providers and semiconductor foundries capture record cash flows, application developers and independent software vendors must re-engineer their unit economics. Survival in late 2026 requires shifting from per-seat billing to consumption and outcome-based pricing models that capture real business productivity.
Hyperscaler capital expenditure and the infrastructure buildout
The scale of capital allocation by Big Tech in 2026 has no precedent in corporate history. Combined quarterly capital expenditures across Microsoft, Alphabet, Amazon, and Meta now exceed $57 billion per quarter, representing an annual run-rate of $228 billion. Wall Street equity analysts initially questioned whether these investments would lead to massive asset impairments. However, latest quarterly financial disclosures indicate that data center capacity remains constrained, with enterprise customer demand outstripping available compute supply through the first half of 2027.
+------------------+-----------------------+-----------------------+-------------------------+
| Hyperscaler | Q3 2026 Annualized | Primary Infrastructure| Cloud Operating Margin |
| Provider | CapEx Run-Rate | Deployment Focus | (Q3 2026 vs Q3 2024) |
+------------------+-----------------------+-----------------------+-------------------------+
| Microsoft Azure | $76.4 Billion | GB200 NVL72 Racks, | 41.2% (down from 44.5%) |
| | | OpenAI Stargate nodes | |
+------------------+-----------------------+-----------------------+-------------------------+
| Amazon AWS | $71.2 Billion | Trainium2 Clusters, | 34.8% (up from 30.2%) |
| | | Graviton4 Compute | |
+------------------+-----------------------+-----------------------+-------------------------+
| Alphabet (GCP) | $52.8 Billion | TPU v5e / v6 Trillium,| 14.6% (up from 3.2%) |
| | | Gemini Serving Fabric | |
+------------------+-----------------------+-----------------------+-------------------------+
| Meta Platforms | $27.6 Billion | Llama 4 Superclusters,| Private Infrastructure |
| | | Ranking Engines | (Internal Meta Family) |
+------------------+-----------------------+-----------------------+-------------------------+
| TOTAL COMBINED | $228.0 Billion | Global Power, Silicon,| Blended Cloud Margin: |
| | | & Real Estate Fleet | ~30.2% |
+------------------+-----------------------+-----------------------+-------------------------+
Microsoft Azure: balancing OpenAI commitments with margin preservation
Microsoft reported Azure revenue growth of 30 percent year over year in constant currency for the most recent quarter. Artificial intelligence workloads contributed 9 full percentage points of that expansion. Microsoft Cloud quarterly gross margin contracted slightly to 69 percent, compared with 71 percent in the corresponding prior-year period. Management cited higher depreciation schedules from accelerated server deployments and long-term lease obligations for power substations in the United States and Northern Europe.
Azure Copilot adoption expanded to 65 percent of the Fortune 500. However, average revenue per user remains modest. Most enterprise clients purchase entry-level tiers at $30 per user per month while limiting deployment to executive and technical staff. To accelerate software monetization, Microsoft introduced Copilot Studio Agent tiers, charging organizations on an execution-per-task basis instead of flat monthly seat licenses.
Alphabet and Google Cloud: operating leverage through custom silicon
Alphabet achieved a milestone in late 2026, recording a 14.6 percent operating margin for Google Cloud, up from 3.2 percent two years prior. Google Cloud revenue reached an annualized pace of $44 billion. Alphabet maintains an economic advantage over rival cloud providers through its internal application-specific integrated circuit program.
Deployments of Google's sixth-generation Tensor Processing Unit, codenamed Trillium, reduced internal inference costs for Gemini models by 60 percent compared to merchant GPU clusters. By serving internal consumer search queries, Google Workspace generative features, and third-party Cloud Vertex AI endpoints on custom silicon, Alphabet shields its consolidated operating margins from merchant hardware price premiums.
Amazon Web Services: the custom silicon counter-offensive
Amazon Web Services generated $110 billion in annualized cloud revenue, expanding at 19 percent year over year. AWS expanded its custom silicon initiatives, scaling commercial availability of Trainium2 instances for frontier model training and Graviton4 processors for general-purpose application hosting.
Amazon's strategic investment of $8 billion into Anthropic cemented AWS as the primary cloud training and distribution partner for the Claude model family. Over 40 percent of Claude 3.5 and Claude 3.7 API volume routes through Amazon Bedrock, allowing AWS to capture high-margin managed service fees without bearing the full operational overhead of proprietary foundation model development.
Meta Platforms: open models as a capital moat
Meta Platforms stands apart from the pure cloud vendors, allocating its $27.6 billion infrastructure budget entirely to internal product optimization and open-source foundation model research. Meta's open-weights strategy with the Llama series commoditized proprietary base models, forcing commercial model providers to reduce developer API prices by over 80 percent between 2024 and 2026.
Meta monetizes its computing infrastructure directly through its digital advertising delivery system. Automated AI content recommendation algorithms, dynamic ad creative generation, and automated messaging agents on WhatsApp and Instagram drove an 18 percent increase in average ad price realization. Meta demonstrated that high infrastructure CapEx can generate immediate free cash flow when tied directly to high-margin core advertising loops.
Semiconductor pricing power: Nvidia, TSMC, and the memory wall
The primary beneficiary of hyperscaler capital expenditure remains the semiconductor hardware supply chain. Market capitalization gains across Nvidia, Taiwan Semiconductor Manufacturing Company, and high-bandwidth memory manufacturers outpaced the broader software sector by a factor of four throughout 2025 and 2026.
Nvidia: managing the transition from Blackwell to Rubin
Nvidia reported quarterly revenue of $36.5 billion, with data center sales accounting for 88 percent of total company earnings. The company maintains gross margins between 73 percent and 75 percent, a level unprecedented for a hardware vendor operating at this revenue scale.
Nvidia Hardware Architectural Evolution:
2024 Hopper (H100/H200) --> 2025 Blackwell (B200/GB200) --> 2026 Rubin (R100/GR200)
- 80B Transistors (4N TSMC) - 208B Transistors (Dual-die 4NP) - 3nm TSMC Architecture
- HBM3 / HBM3e Memory - 192GB HBM3e (8 TB/s Bandwidth) - HBM4 Memory (16-Hi Stacks)
- Air and Liquid Cooled - Full NVL72 Liquid-Cooled Rack - Optical Interconnect Fabric
- Average System Price: $35k - Rack Price: $2.8M - $3.2M - Rack Price: $3.8M - $4.4M
Production constraints shifted from raw wafer fabrication to advanced packaging and thermal management. The Blackwell GB200 NVL72 platform, which connects 72 GPUs and 36 Grace CPUs into a single liquid-cooled rack operating as one unified processor, requires 132 kilowatts of power per cabinet. High-density data center operators must retrofit electrical distribution systems and deploy direct-to-chip liquid cooling loops to support these workloads.
Initial technical specifications for Nvidia's next-generation Rubin platform, scheduled for production ramp in early 2027, introduce native optical chip-to-chip interconnects and HBM4 high-bandwidth memory. By controlling the CUDA software ecosystem, the NVLink switching fabric, and server rack reference designs, Nvidia prevents cloud providers from treating compute hardware as an interchangeable commodity.
TSMC and the packaging bottleneck
Taiwan Semiconductor Manufacturing Company operates at 100 percent capacity utilization across its 3-nanometer and 4-nanometer foundry nodes. However, the true supply bottleneck in 2026 is Chip-on-Wafer-on-Substrate packaging.
Every advanced AI accelerator, whether produced by Nvidia, AMD, or Google, requires CoWoS advanced packaging to place high-bandwidth memory silicon adjacent to the main compute dies. Despite TSMC expanding its dedicated advanced packaging facilities in Chiayi and Tainan by 120 percent, demand for advanced packaging exceeds available output by 25 percent.
This supply bottleneck guarantees sustained pricing power for TSMC. It also benefits South Korean memory manufacturer SK Hynix, which supplies more than 60 percent of global HBM3e and HBM4 memory modules, maintaining operating margins above 45 percent in its memory division.
Technical visual asset 2: the AI capital and revenue flow architecture
Figure 2: Architectural pipeline diagram mapping the flow of capital and gross margins across silicon foundries (74% margin), hyperscale cloud (32% margin), frontier model labs (variable/break-even), and enterprise software applications (compressed multiples). View or download full-size PNG on Google Drive.
Midjourney v6 / FLUX.1 generation prompt:
A technical process flow diagram showing four connected stages of software and compute infrastructure. Modular glass rectangular stages glowing with neon accents: first stage emerald green silicon, second stage cyan hyperscale cloud, third stage amber neural model labs, fourth stage magenta enterprise software. Connected by fiber-optic directional pipelines on a matte dark background, isometric perspective, clean engineering schematics, 4k resolution --ar 16:9
The B2B SaaS multiple compression and the death of seat-based pricing
The most significant structural development in the software industry during 2026 is the compression of public and private software company valuations. Between 2018 and 2022, cloud software companies traded at median enterprise value to forward revenue multiples of 12 times, with top-quartile performers like Snowflake, Datadog, and Cloudflare commanding multiples exceeding 30 times.
By Q3 2026, the median enterprise software multiple contracted to 5.8 times next-twelve-months revenue. This valuation adjustment is not merely an interest-rate phenomenon; it represents a fundamental change in how corporate software is purchased and priced.
Historical Software Multiples (EV / Forward Revenue Median):
2021 (Peak SaaS Bubble) : [====================================] 14.8x
2023 (Post-Pandemic Rate Reset): [====================] 7.2x
2024 (Early AI Expansion) : [==================] 6.9x
2026 (Current Q3 Market) : [===============] 5.8x
The structural crisis of seat-based licensing
For two decades, the software-as-a-service business model operated on a straightforward growth formula: sell software on a per-user, per-month basis, and expand annual recurring revenue as client headcount grew.
The deployment of autonomous AI agents in 2025 and 2026 disrupted this equation:
- In software engineering, autonomous coding agents like Claude Code, Cursor, and GitHub Copilot Workspace allowed development teams to produce twice the code volume with 20 percent fewer junior engineering hires. Consequently, engineering departments reduced seat counts on developer tooling platforms.
- In customer support, autonomous voice and text agents resolved 60 to 75 percent of incoming support tickets without human agent intervention. Customer support platforms that charged $80 per human support seat saw their contract values decrease during enterprise renewal cycles.
- In corporate finance and HR, workflow automation agents processed invoicing, expense auditing, and employee onboarding without requiring individual user licenses for every internal stakeholder.
Enterprise software companies that tied their revenue growth to employee headcount face stagnating net revenue retention rates. NRR figures that previously averaged 115 to 125 percent among top SaaS firms have dropped to 102 to 106 percent across the industry.
The rise of outcome-based and work-metered monetization
To counter multiple compression, leading enterprise software vendors are redesigning their pricing architecture. Salesforce launched its Agentforce platform in late 2024 and completed a pricing transition in 2026, charging customers $2 per completed autonomous agent conversation without requiring additional user seats.
Pricing Model Transition Framework:
Legacy Model (2015-2024) --> Transition Model (2025-2026) --> Emergent Standard (2026+)
- Per-Seat / Per-User License - Base User Seat + AI Add-on ($30/mo) - Work-Metered / Outcome Billing
- Value Tied to Human Labor - Token Consumption Metering - Fee Per Completed Business Task
- Predictable, Rigid Budget - Variable Utility Billing - SLA-Backed Economic Value Pricing
ServiceNow adopted a similar strategy with its Pro Plus and Enterprise tiers, charging clients based on workflow transactions and automated incident resolution counts. Early financial data shows that enterprise clients accept outcome-based billing when the economic ROI is measurable: paying $2 to resolve a customer support inquiry that previously cost $18 in human labor represents an immediate 88 percent cost reduction.
However, software vendors face margin pressure during this transition. A traditional SaaS gross margin of 80 to 85 percent reflects low AWS or Azure server hosting costs. When an application vendor embeds deep reasoning models like OpenAI o3 or Claude 3.7 into every user interaction, inference API costs consume 10 to 25 percent of gross contract value, compressing software gross margins toward 68 to 74 percent.
Frontier AI lab economics: OpenAI and Anthropic market penetration
The economic battle between the primary independent foundation model laboratories, OpenAI and Anthropic, intensified in 2026 as both organizations transformed from research entities into enterprise software powerhouses.
OpenAI: high revenue scale against severe capital burn
OpenAI achieved an annualized revenue run-rate approaching $12 billion in the third quarter of 2026, representing a 200 percent increase over mid-2024 figures. Revenue generation splits across three distinct channels:
- Enterprise ChatGPT and Team subscriptions: $5.2 billion ARR.
- Direct developer and enterprise API token consumption: $4.4 billion ARR.
- Microsoft intellectual property licensing and revenue-sharing royalties: $2.4 billion annualized.
Despite this revenue growth, OpenAI remains cash-flow negative. Training next-generation frontier models, including the Orion architecture and iterative reasoning updates (o-series), requires dedicated compute clusters costing between $3 billion and $6 billion per training run.
Inference compute represents an ongoing financial demand. The introduction of reasoning models, which generate hidden internal chains of thought before delivering a final answer, increased token consumption per query by a factor of 10 to 50 compared to standard conversational models. While users pay $200 per month for premium ChatGPT Pro tiers, heavy developer usage routinely exhausts the operational compute allocated to individual accounts.
To secure long-term capital independence, OpenAI restructured its corporate governance in 2025 and 2026, transitioning from its historical non-profit control model to a public benefit corporation. This transition paved the way for massive sovereign wealth and corporate funding rounds valuing the company above $160 billion, while laying the operational groundwork for an anticipated public listing in late 2027.
Anthropic: dominance in developer tooling and enterprise safety
Anthropic cemented its position as the preferred foundation model provider for technical enterprises and software engineering teams. The company reached an annualized revenue run-rate of $3.6 billion in Q3 2026, growing at a faster percentage clip than any of its direct competitors.
Anthropic's commercial success centers on its Claude model family:
+----------------------------+-----------------------------+------------------------------+
| Metric / Capability | OpenAI (GPT-4o / o1 / o3) | Anthropic (Claude 3.5 / 3.7) |
+----------------------------+-----------------------------+------------------------------+
| 2026 Annualized Revenue | ~$12.0 Billion | ~$3.6 Billion |
| Primary Cloud Distribution | Microsoft Azure | Amazon AWS & Google Cloud |
| Developer Mindshare Focus | General Consumer, Business | Software Engineering, Logic, |
| | Voice, & Multimodal Creative| Coding Agents, & Analysis |
| Coding Benchmark Dominance | Swe-Bench: ~65% - 70% | Swe-Bench Verified: 75%+ |
| Governance Structure | Public Benefit Corporation | Long-Term Benefit Trust |
| Model Architecture Focus | Extended Reasoning (o-series)| Hybrid Fast / Deep Reasoning |
+----------------------------+-----------------------------+------------------------------+
Anthropic captured dominant market share within modern software engineering workflows. Development environments including Cursor, GitHub Copilot, Replit, and the Claude Code command-line interface report that over 65 percent of developer token volume routes to Claude 3.5 and 3.7 Sonnet. Programmers prefer Claude's adherence to multi-file code editing instructions, lower syntax hallucination rates, and predictable architectural planning.
Anthropic's dual distribution model through Amazon Web Services and Google Cloud provides enterprise procurement teams with multi-cloud flexibility. Corporations reluctant to direct their proprietary data through Microsoft Azure utilize Anthropic models inside their existing AWS VPCs or Google Cloud projects, ensuring compliance with strict data residency mandates.
Apple and consumer device software: edge inference and Private Cloud Compute
While cloud providers and model labs compete on server-side model parameters, Apple executes a consumer device strategy focused on edge inference efficiency and hardware upgrade cycles.
Apple Intelligence and the silicon replacement cycle
Apple's financial results for fiscal 2026 demonstrated sustained resilience, with quarterly revenue reaching $94 billion. The rollout of Apple Intelligence across iOS 18, iOS 19, and macOS Sequoia drove an acceleration in iPhone and Mac replacement cycles.
Apple's architecture relies on a hybrid tiering strategy:
- On-device small language models (SLMs): Standard text summarization, notification prioritization, photographic manipulation, and quick email drafting execute entirely on-device using a 3-billion-parameter foundation model. This model runs locally on the 16-core Neural Engine of Apple A18 Pro and M4 processors, consuming zero cloud compute and operating with zero latency.
- Private Cloud Compute (PCC): When a user query requires complex reasoning, Apple routes the request to custom data centers powered by Apple Silicon server clusters (M-series processors running a hardened, memory-safe operating system). Apple cryptographically guarantees that user data is never retained on disk, cannot be inspected by Apple personnel, and is deleted immediately upon query completion.
- Third-party frontier partnerships: For open-ended factual queries and general world knowledge, Apple offloads requests to OpenAI's ChatGPT and Google's Gemini, requiring explicit user consent before transmitting any data off the Apple ecosystem.
Apple Hybrid Inference Processing Architecture:
User Request Generated on iPhone / Mac
|
+---> Query Evaluator (On-Device Local Dispatcher)
|
+---> Simple / Sensitive Task? ---> Processed locally on A18/M4 Neural Engine (0ms Cloud Latency)
|
+---> Complex Contextual Task? ---> Routed to Private Cloud Compute (Apple Silicon Server Nodes)
|
+---> World Knowledge / Research? -> Handed off to Third-Party API (ChatGPT / Gemini with Consent)
Services margin expansion and developer ecosystem control
Apple's Services division reached record annualized revenue of $100 billion, operating with gross margins of 74.5 percent. By integrating AI features directly into system-level frameworks (App Intents, Siri 2.0, and CoreML), Apple established a distribution gateway that third-party software developers must adopt.
Developers building iOS and macOS software must adapt their apps to system intents or risk losing discoverability to built-in system agents. By maintaining control over the mobile operating system interface, Apple monetizes the AI transition through App Store commission structures and expanded iCloud subscription tiers without assuming the multi-billion-dollar merchant GPU capital commitments of its hyperscale peers.
Analytical visual asset 3: software valuation and margin matrix
Figure 3: Comparative valuation matrix detailing enterprise value multiples, gross margins, pricing models, and primary vulnerability factors across modern software sectors in 2026. View or download full-size PNG on Google Drive.
Midjourney v6 / FLUX.1 generation prompt:
A clean, high-contrast financial evaluation table card floating on a dark reflective surface. Column headers in crisp white typography against a deep charcoal card, featuring data cells with glowing green gross margins, cobalt blue enterprise value multiples, and red risk callouts. Professional institutional equity research presentation, 8k resolution, minimalist editorial aesthetic --ar 16:9
Structured comparative analysis: 2026 tech sector financial metrics
The following comparative table summarizes the financial profiles, valuation multiples, and structural operational models governing the four primary tiers of the global technology sector in Q3 2026:
Industry Tier | Leading Market Players | EV / Forward Revenue Multiple | Gross Margin Profile | Primary Revenue Model | Key Operational Bottleneck |
Semiconductor & Foundry | Nvidia, TSMC, SK Hynix, Broadcom | 18.5x – 24.0x | 72% – 76% | High-Margin Physical Hardware & Systems | CoWoS Advanced Packaging, HBM4 Yields, Power |
Hyperscale Cloud | Microsoft Azure, AWS, Google Cloud | 8.5x – 10.2x | 65% – 69% | Compute Consumption & Capacity Subscriptions | Megawatt Power Interconnects & High CapEx Depreciation |
Frontier Model Labs | OpenAI, Anthropic, DeepMind | 25.0x – 35.0x (Private) | 35% – 50% (Post-Inference) | Per-Token API Metering & $20-$200/mo Subscriptions | Multi-Billion Training Cluster Expense & Reasoning Inference |
Legacy B2B SaaS | Salesforce, Workday, ServiceNow, Adobe | 5.5x – 6.5x | 70% – 76% (Compressing) | Per-Seat Recurring Licenses + Emerging Agent Tiers | Seat Contraction via Agent Automation & Inference COGS |
Open-Source & Self-Hosted | Supabase, PostHog, Coolify, Docker | Private (High ARR Growth) | 80%+ (Enterprise Support / SLA) | Self-Hosted Open Core + Enterprise Managed Cloud | Requires Internal Technical DevOps Expertise to Manage |
Strategic recommendations for software engineering leaders and founders
The macroeconomic and structural shifts underway in late 2026 require technical founders, CTOs, and software product leaders to adjust their operational playbooks. Strategies that generated high software multiples during the low-interest-rate, seat-expansion era no longer work.
Operational Adjustment Checklist for Software Leaders:
1. Pricing Strategy : Decouple revenue from employee headcount; implement work-metered billing.
2. Architecture Routing : Deploy multi-model gateways to avoid sole-source token dependence.
3. Cost Governance : Implement prompt caching, semantic vector cache, and SLM distillation.
4. Infrastructure Split : Hybridize workloads between cloud elasticity and predictable bare-metal hosting.
1. Decouple your revenue model from customer headcount
If your software product charges $50 per user per month, your business is economically misaligned with client efficiency goals. If an AI coding agent or autonomous workflow tool cuts a client's team size by 30 percent, your monthly contract will decline automatically.
Shift pricing toward work units, completed transactions, or revenue-impact milestones. Charge directly for the output produced by the system.
2. Implement a multi-model abstraction layer
Never hardcode your application logic directly to a single foundation model provider. The pricing and latency dynamics change every three months. An enterprise relying solely on OpenAI o1 or o3 risks gross margin deterioration if an equivalent task can be executed at one-tenth the cost using Claude 3.5 Haiku, Gemini 2.0 Flash, or an open-weight model like Llama 4 running on a private vLLM server.
Deploy gateway routers that evaluate query complexity in real time, routing simple conversational interactions to lightweight local models and reserving high-cost reasoning models for complex analytical tasks.
3. Implement aggressive token cost optimization
Unmonitored LLM inference will destroy software gross margins. Engineering teams must implement three non-negotiable optimization patterns:
- Prompt caching: Cache repetitive system instructions, extensive database schemas, and documentation embeddings. Both Anthropic and OpenAI support prompt caching, reducing repeated input token costs by up to 90 percent.
- Semantic caching: Store frequently asked queries and validated answers in a local Redis vector database to bypass external LLM API calls entirely for common requests.
- Model distillation: Use expensive frontier models to generate synthetic training datasets, then fine-tune compact 8-billion-parameter open models to perform specialized classification and data extraction tasks on local VPS infrastructure.
4. Hybridize between hyperscale cloud and bare-metal infrastructure
Relying entirely on hyperscale managed services exposes growing startups to severe bandwidth and compute markups. Modern engineering teams run stateful, predictable workloads on high-performance dedicated servers or virtual private servers (such as Hetzner, Hostinger, or OVHcloud) while leveraging AWS or Azure exclusively for dynamic burst capacity and specialized managed services.
Operating database clusters, internal caching tiers, and background worker queues on bare metal can reduce monthly infrastructure expenditures by 60 to 80 percent, restoring the gross margins necessary to attract institutional growth capital.
Frequently asked questions (FAQ) for search and answer engines
Why have software-as-a-service valuation multiples compressed in 2026?
Software-as-a-service valuation multiples have compressed from historical medians of 12x to 15x forward revenue down to 5.8x in 2026 due to two primary structural factors: the disruption of seat-based licensing models by autonomous AI agents, and gross margin compression caused by recurring LLM inference compute costs. As companies use AI tools to accomplish more work with fewer employees, software products priced per seat experience lower net revenue retention and slower annual expansion.
How much are hyperscalers spending on AI infrastructure in 2026?
The four largest hyperscale technology companies, Microsoft, Alphabet, Amazon, and Meta, are investing an annualized capital expenditure total of $228 billion in 2026. This capital is allocated toward physical data center construction, electrical grid infrastructure, liquid cooling systems, and advanced semiconductor accelerators including Nvidia Blackwell and custom internal processors like Google TPUs and AWS Trainium.
What is the difference between seat-based pricing and outcome-based pricing?
Seat-based pricing charges a fixed recurring monthly fee for every human employee who has login access to a software application, tying vendor revenue directly to customer headcount. Outcome-based pricing charges customers based on completed business deliverables, such as a successfully resolved customer support conversation, an audited invoice, or an automated code deployment, tying vendor revenue to measurable business output.
Why is Nvidia able to maintain gross margins above 70 percent?
Nvidia maintains gross margins between 73 and 75 percent because it controls a near-monopoly on the full hardware and software computing stack for artificial intelligence. By bundling graphics processing units with its proprietary CUDA software libraries, NVLink optical switching systems, and complete server rack reference architectures, Nvidia prevents enterprise cloud providers from substituting its hardware with generic silicon commodities.
How does Apple's AI strategy differ from Microsoft and Google?
While Microsoft and Google focus primarily on server-side hyperscale cloud inference, Apple prioritizes edge inference on local consumer devices. Apple executes approximately 70 percent of routine AI queries on the local neural engines of iPhone and Mac chips, offloading complex tasks to private Apple Silicon servers running Private Cloud Compute, and only routing open-ended factual research to third-party providers with explicit user consent.
What is the primary hardware supply bottleneck for AI in late 2026?
The primary hardware supply bottleneck in late 2026 is not raw silicon wafer production, but Chip-on-Wafer-on-Substrate (CoWoS) advanced packaging at Taiwan Semiconductor Manufacturing Company (TSMC) and the supply of high-bandwidth memory (HBM3e and HBM4) manufactured by SK Hynix, Samsung, and Micron. Placing high-speed memory directly adjacent to processing silicon requires advanced packaging techniques that currently operate at 100 percent global capacity utilization.
Build resilient, high-margin software infrastructure
Navigating the technology market in late 2026 requires balancing computational power against strict financial discipline. Companies that rely on outdated pricing models or unmonitored cloud spending will see their operating margins diminish as infrastructure costs mount.
If your organization needs to build scalable cloud architectures, transition legacy SaaS products to consumption-based pricing, or implement custom open-source AI workflows, connect with the engineering team at Buzzin Tech to engineer modern software systems that deliver sustainable profitability.